
· 15 min read
How to Set Up Reddit Keyword Monitoring and Get Telegram Alerts with A-Parser: Using r/Oktoberfest as an Example
1. Why Keyword Search Alone Is Not Enough for Reddit Monitoring
Every day, people publish product reviews, service requests, incident reports, and time-sensitive offers on Reddit. The challenge is not finding one relevant post; it is continuously spotting new ones among duplicates and general discussion.
Reloading a page periodically or searching for exact keyword matches is not enough. A practical monitor has to solve four problems.
- Collect data reliably on a schedule. A one-off request to a public Reddit page may work, but automated monitoring must account for access restrictions, request limits, network errors, and changes in the response format. A custom solution would also need retries, logging, and result storage. Depending on collection volume, proxies may be required.
- Distinguish a keyword from the author’s intent. Suppose the monitor tracks
ticket,table, andseat. These words may appear in a question about booking rules, a discussion of ticket prices, a warning about a suspicious seller, or a specific offer of two available seats. The words are similar, but each post requires a different response. - Separate target events from ordinary community posts. Even in a relevant subreddit, most discussions may not match the monitor’s specific purpose. Users in
r/Oktoberfestask about weather, clothing, transport, and travel plans. These posts are useful and are not spam, but they do not require an alert for someone waiting for an available seat. - Avoid processing the same posts repeatedly. A new-post feed changes gradually. If it is collected every 15 minutes without retaining history, many posts will be processed again. The monitor therefore needs to remember a stable ID or URL for every item it has already seen.
The real question goes beyond a simple keyword search:
Has a new event appeared since the previous check that matches our rules and requires attention?
Why r/Oktoberfest Is a Useful Example
Oktoberfest lasts only a few weeks, from September to early October, so the date and response time matter. While some members of r/Oktoberfest discuss Munich weather, what dirndl to wear, or how to reach Theresienwiese, others publish posts such as: “Two seats became available in a tent on the evening of September 26.”
An offer like this is easy to miss among general questions, and it may no longer be relevant the next day. This makes r/Oktoberfest a clear example of the difference between ordinary post collection and event monitoring: it is not enough to spot a new post; the system must recognize a time-sensitive event tied to a date, a number of seats, and a particular tent.
In many tents, reservations are made for groups of seats or entire tables, and the terms vary by date and organizer. A small group may not want to book a full table, so users look for a chance to join another party. Conversely, when a group’s plans change, it may offer the seats that became available.
A target signal for the monitor may look like this:
“Our plans changed and two seats at a table are now available for a specific date. Send me a private message if you would like to join.”
Dozens of posts about weather, clothing, transport, and festival rules appear alongside an offer like this. A search for table cannot always distinguish an available seat from a general booking question. A semantic filter can distinguish the two, while the deduplication database prevents the same post from being sent twice.
During the test, the monitor reviewed approximately one hundred recent posts and sent 18 Telegram alerts about available seats, requests for seats, and people looking for companions. The remaining posts did not pass the filters. We will review the detailed results and model limitations below.
The same principle can be used for brand monitoring, finding service requests, support triage, and incident detection. The source and relevance criteria change, but the logic remains the same: collect new items, remove duplicates, determine intent, and send a concise alert.
2. Architecture: a Three-Task A-Parser Pipeline
The A-Parser workflow uses three built-in parsers. Each handles a separate operation, and its output is passed automatically to the next stage.
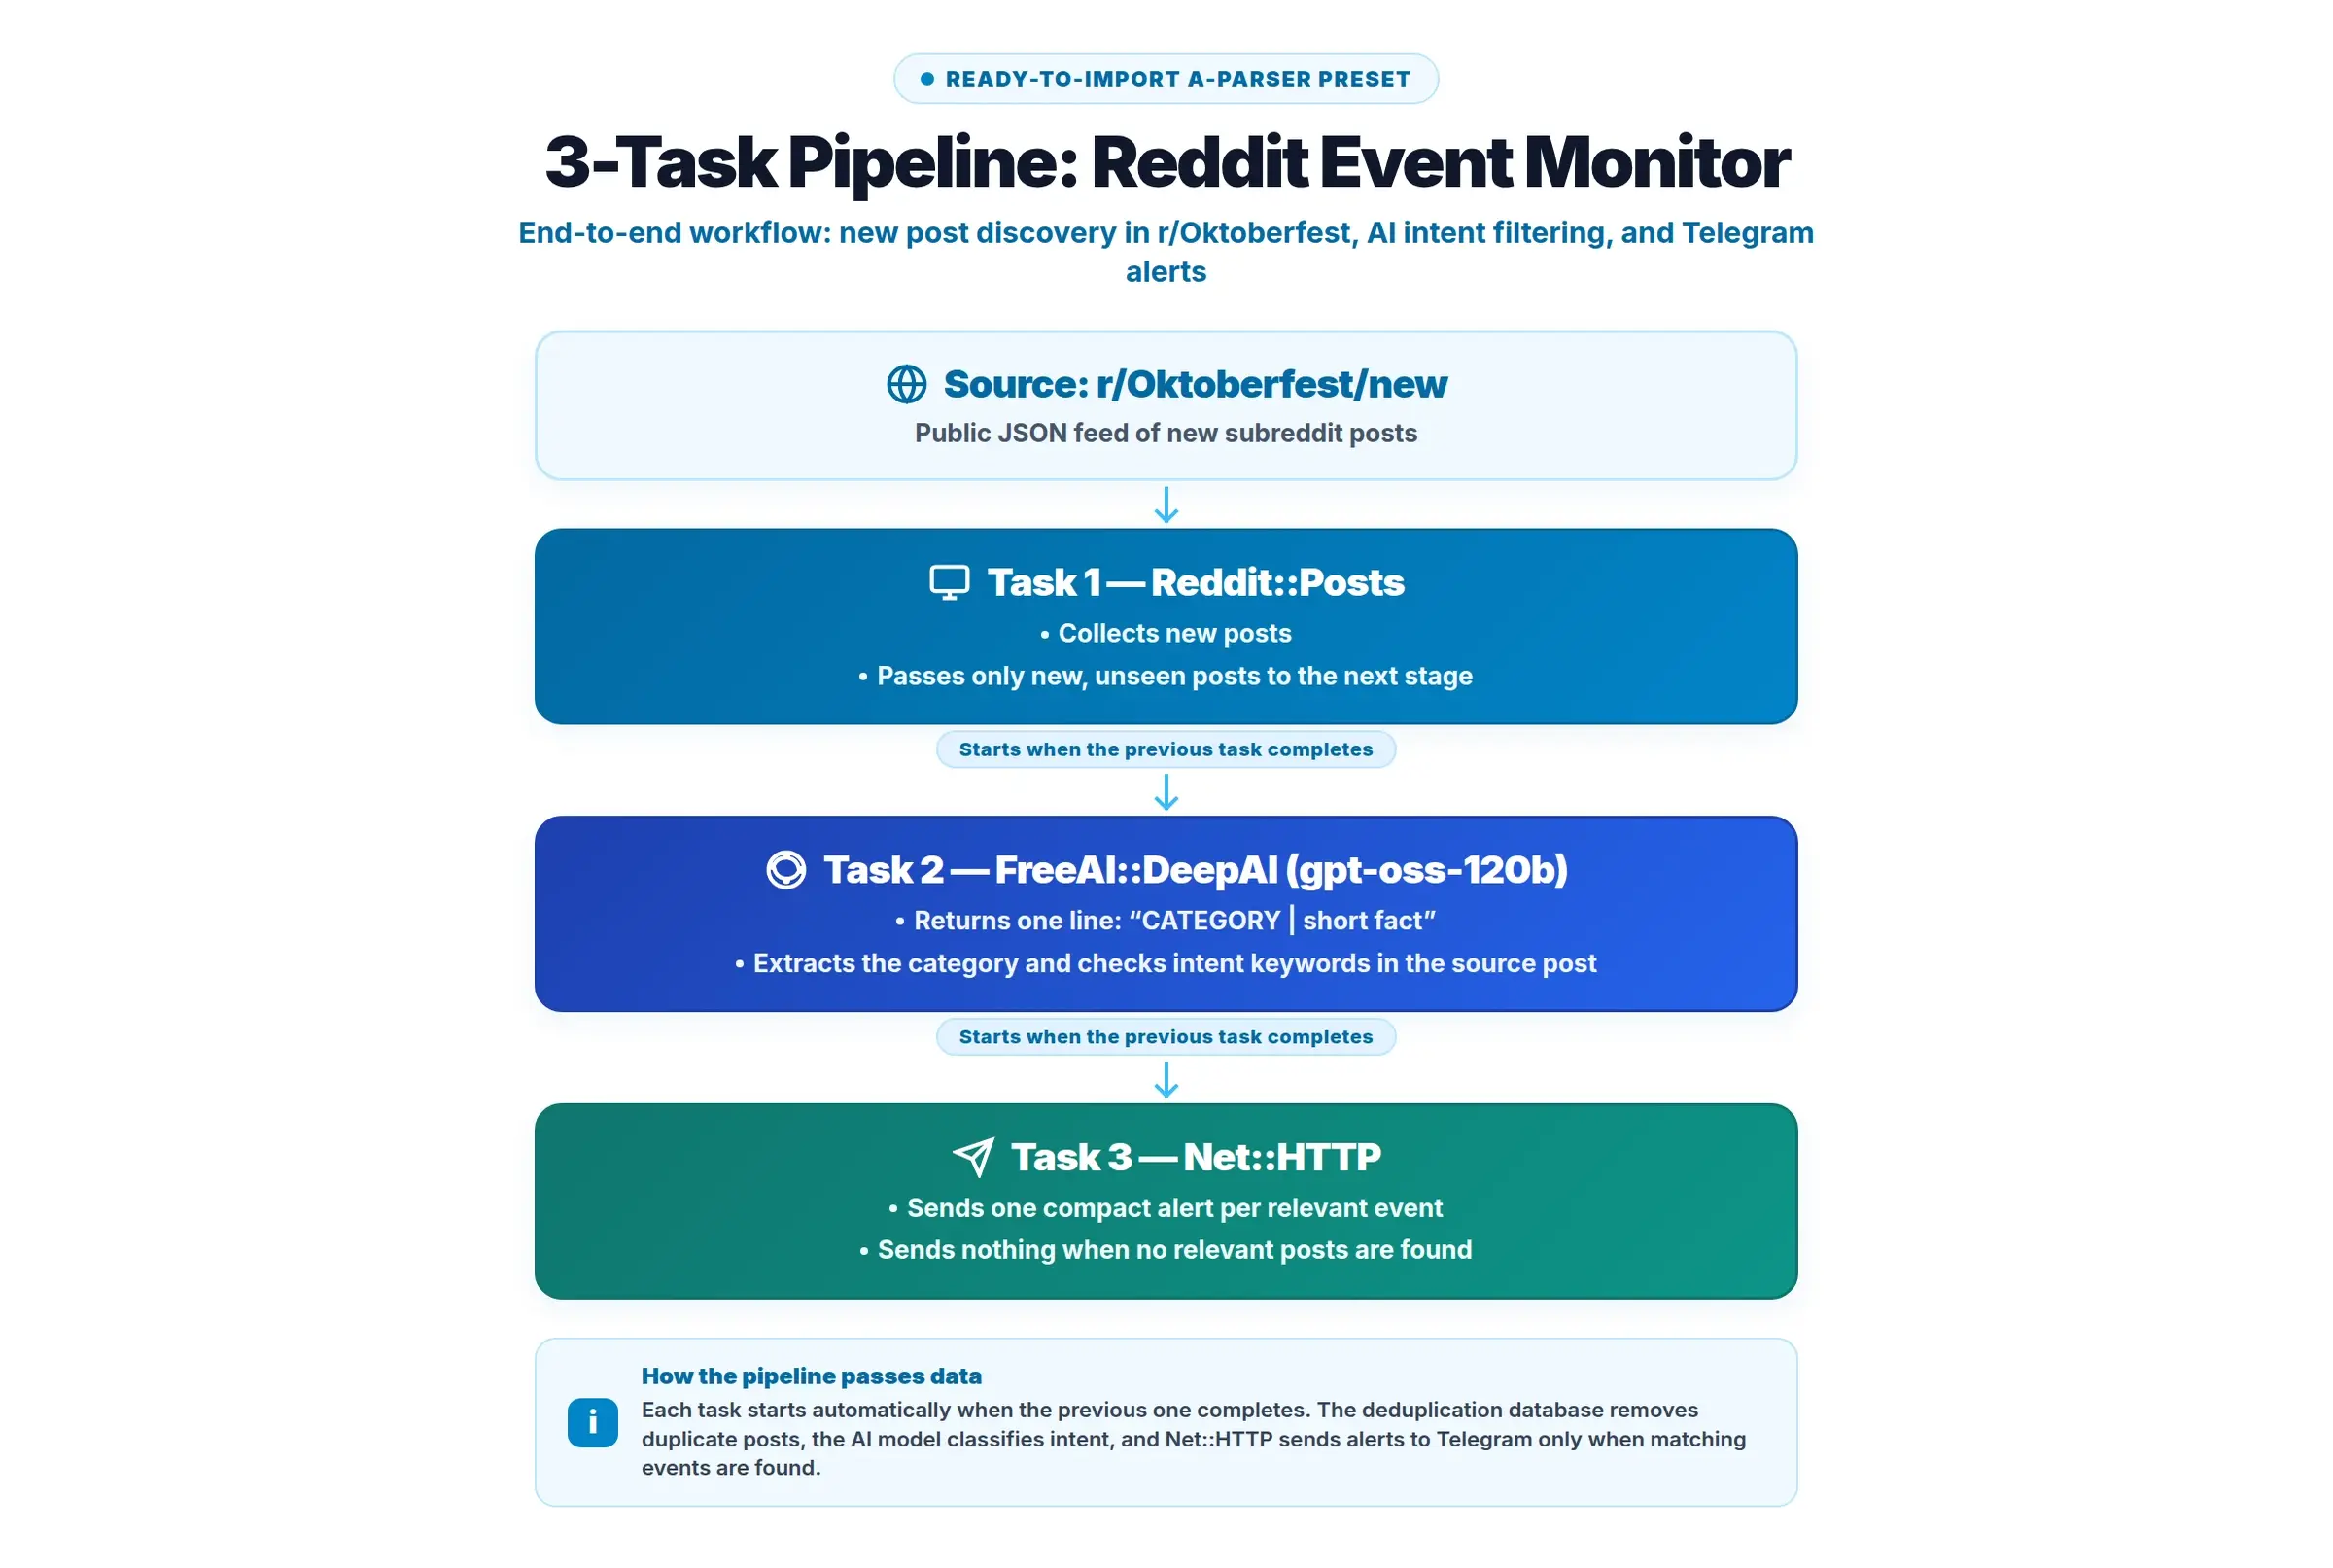
The system tracks three types of information without requiring an external database:
| State | Where It Is Stored | Why It Matters |
|---|---|---|
| Memory: which posts have already been seen | A-Parser’s built-in deduplication database | Prevents repeated AI requests and duplicate alerts |
| Relevance: which posts match the target event | FreeAI::DeepAI output plus deterministic title/body checks | Separates an important event from background noise |
| Delivery channel: where to send the result | Net::HTTP parser settings | Provides immediate delivery without an external webhook service |
How the Tasks Pass Results to One Another
The output of each task automatically becomes the input of the next one. The first stage passes only new posts. The second extracts SELL, BUY, COMPANY, ALERT, or NO_MATCH from the model’s response and then validates the category against the original title and body. NO_MATCH and posts that fail the checks produce no result line. The third task sends one separate Telegram POST for every remaining line.
This allows the chain to run without manual data transfer. If there are no matching posts, execution ends without a notification.
3. Step 1: Collect Only New Posts
The first stage monitors recent posts in the selected subreddit. In this example, the built-in Reddit::Posts parser checks the r/Oktoberfest feed and retrieves the title, body, and URL of each post.
However, the new-post feed changes gradually. The next run will still include posts seen during the previous check. Sending the full list to the model every time would analyze old posts again and could produce duplicate alerts.
To prevent this, A-Parser compares the stable post URL in posts.link with stored URLs. The history is kept in the redditArticleSeen database, so previously seen posts are not passed to DeepAI again.
The logic is straightforward:
First run:  A, B       → pass A and B
Second run: A, B, C    → pass only C
Third run:  A, B, C    → pass nothing
The parser loads the Reddit feed on every run, but only new URLs are included in the output and passed to the next task.
Deduplication answers only one question: have we seen this post before? It does not yet determine whether the post is useful. A new question about the weather is still a new item, but the semantic filter at the next stage will remove it.
As a result, the model analyzes only new posts and the user does not receive repeated alerts about events that the monitor has already processed.
4. Step 2: DeepAI Suggests a Category, A-Parser Validates It
Once deduplication is complete, each post is sent to FreeAI::DeepAI using the gpt-oss-120b model. The model analyzes the title and body and proposes one of five labels.
| Label | Meaning |
|---|---|
SELL | The author offers a ticket, reservation, or available seat |
BUY | The author is looking for a ticket, seat, or reservation |
COMPANY | The author is looking for companions or a group |
ALERT | The author warns about fraud, a ticket problem, or an important restriction |
NO_MATCH | The post does not describe a target event |
Processing has two stages:
Reddit post
→ DeepAI category
→ title and body validation in A-Parser
→ alert or silence
DeepAI receives the original URL, title, and post body, then returns one line in the format CATEGORY | short fact. For example:
SELL | The author offers seats at a table for a specific date.
The model response is treated as a candidate rather than a finished alert. A-Parser extracts the category label and validates it against the original post. For SELL and BUY, the source text must contain references to tickets, seats, tables, or reservations, together with the corresponding intent. COMPANY and ALERT have separate checks. Posts about hotels, clothing, apps, services, and general advice are excluded.
If the model returns NO_MATCH, or if the source post fails validation, no message is created. The short fact from DeepAI is used only for diagnostics. The title and URL in the final alert are taken directly from Reddit.
This separation reduces the risk of a false alert: DeepAI helps interpret the stream, while A-Parser validates the proposed category against the source data. The system does not verify that a ticket is genuine, that a seller is trustworthy, or that the author’s claims are accurate.
5. Step 3: Get a Telegram Alert
After semantic filtering, Net::HTTP sends every matching result to Telegram as a separate HTTP POST. There is no need to develop a separate bot service or transfer data manually: delivery remains part of the same A-Parser chain.
The message contains only the information needed to decide whether to open the post and contact its author:
- the event category;
- the original Reddit post title, truncated to a safe limit;
- a link to the original post.
For example, a final alert may look like this:
SELL | 4 table spots at Schützenlisl 26-09-2026 | https://www.reddit.com/…
If several matching posts are found during one run, each produces a separate compact alert with a link to the source post. If no target events are found, no message is sent.
Telegram therefore does not become a copy of the Reddit feed. The user receives a notification only when a new post matches the specified rules and can open that post’s original URL.
Telegram is only one possible delivery channel. The same final stage can send results to a team chat, CRM, or another service that accepts HTTP requests.
6. Run the Monitor on a Schedule
For r/Oktoberfest, we configured a check every 15 minutes. The chain then works without user involvement: it checks the latest feed, passes new posts to DeepAI, and sends an alert only when a post passes the filters. If no matching event is found, Telegram remains silent.
In the recorded test run, collection took about six minutes. Classifying 101 posts using four threads took another six and a half minutes, while delivery took less than one minute. A regular run will usually contain fewer new posts and may finish faster.
The right interval depends on how quickly an event becomes irrelevant. Available-seat offers should be checked frequently, while review collection or product research may use a longer interval.
7. Results of the r/Oktoberfest Test
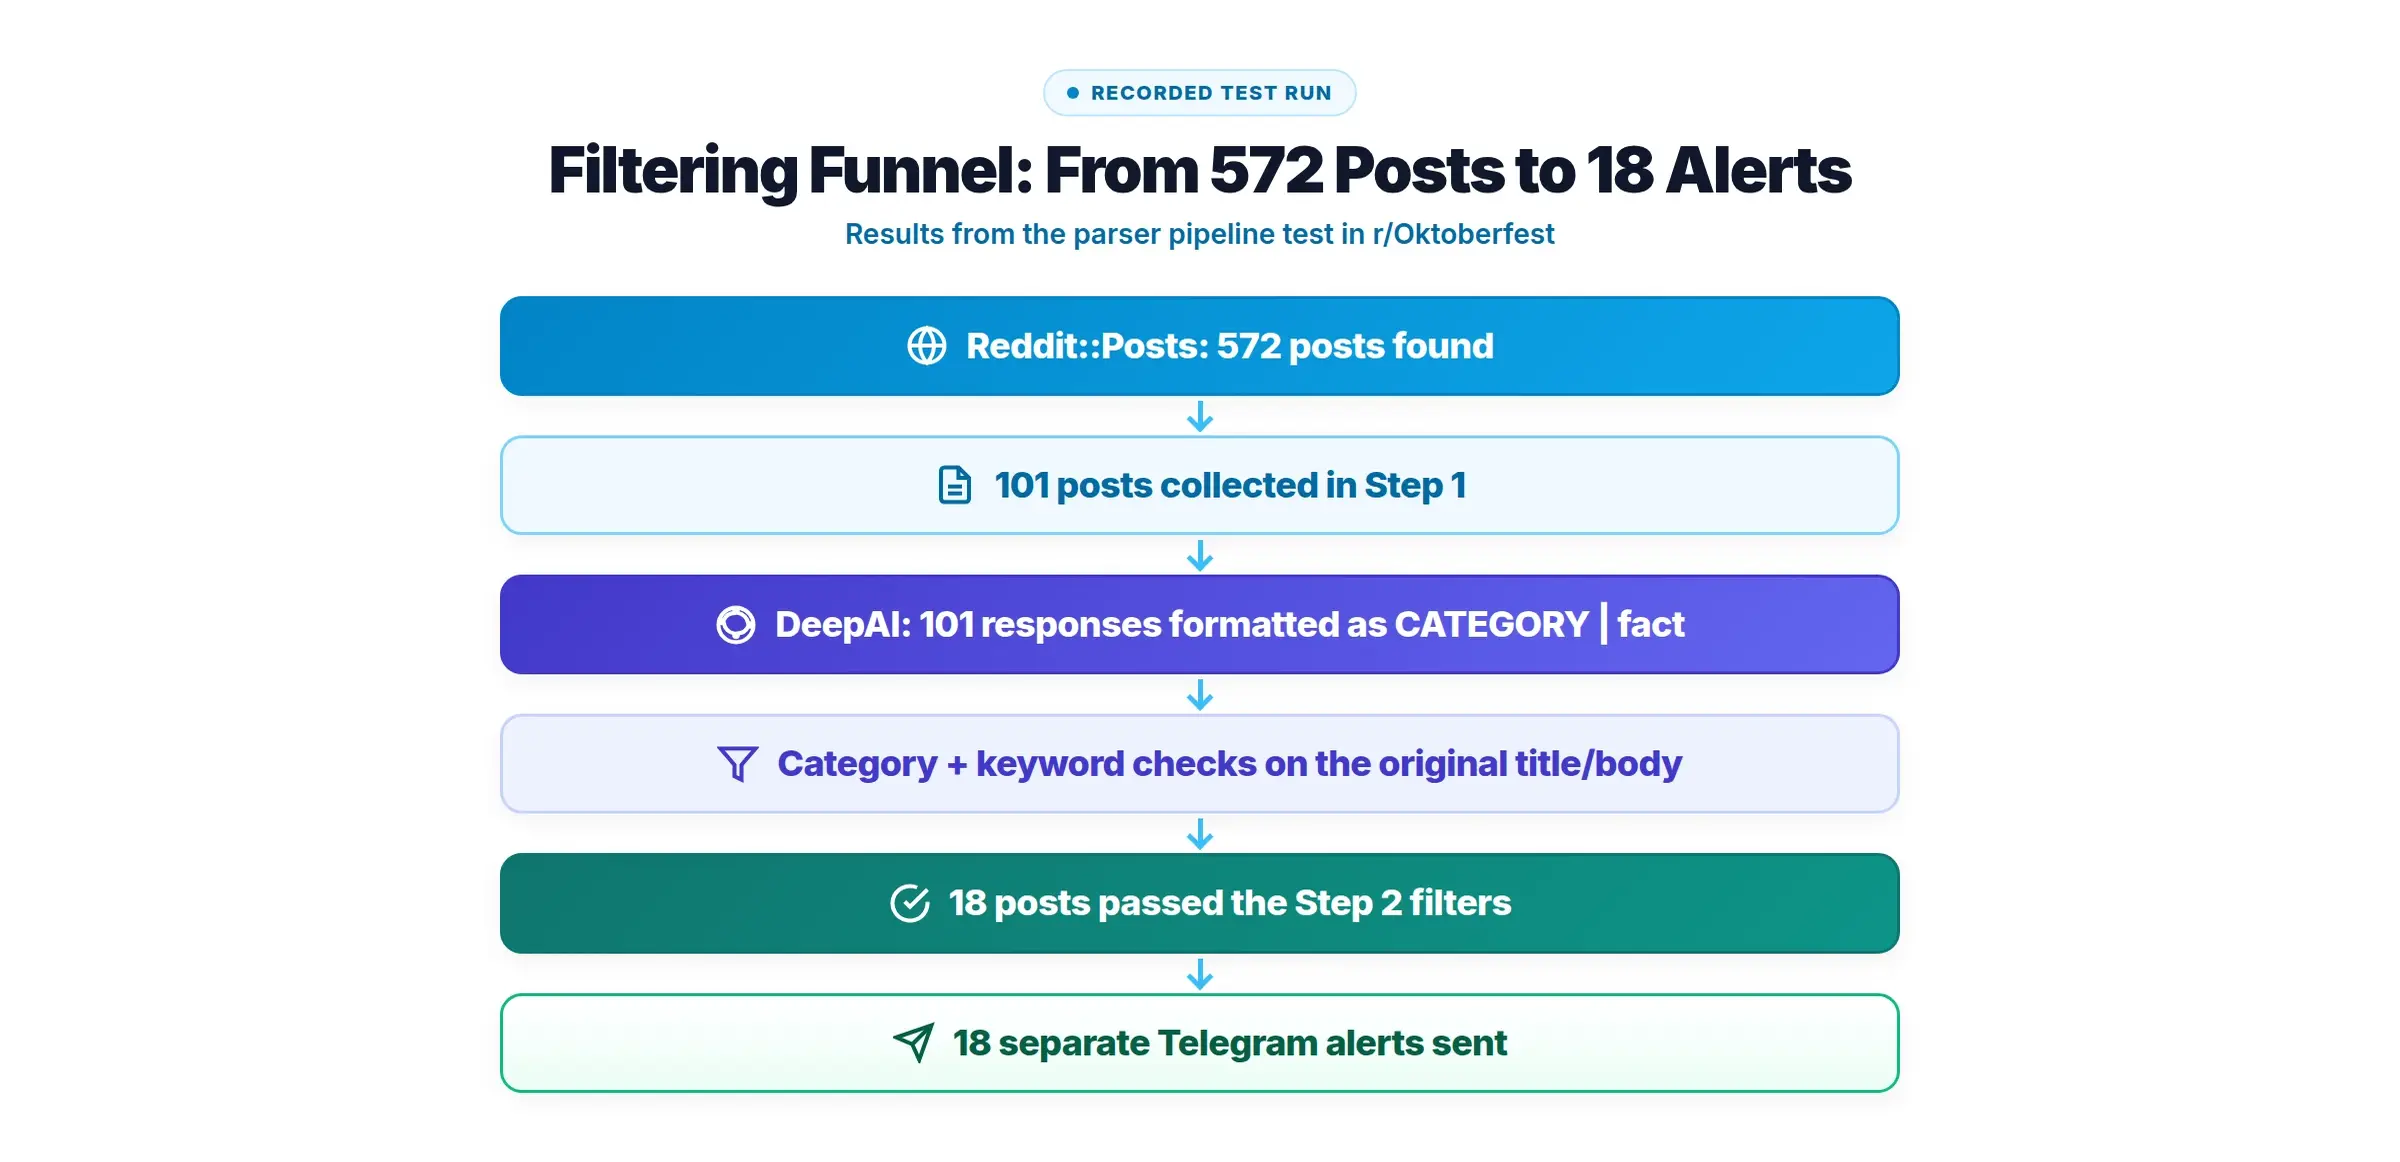
The test was planned for approximately 100 posts, and the chain processed 101. The results of that run are shown below.
| Metric | Test Result |
|---|---|
| Posts found by the Reddit parser | 572 |
| Collected and classified | 101 |
| Answers in `CATEGORY | fact` format |
Model answers: SELL | 34 |
Model answers: BUY | 28 |
Model answers: COMPANY | 12 |
Model answers: ALERT | 2 |
Model answers: NO_MATCH | 25 |
| Passed all filters and sent | 18 |
| Alert breakdown | 10 SELL, 4 BUY, 4 COMPANY |
| Telegram responses | 18 of 18 — HTTP 200 |
| Check interval | 15 minutes |
| Collection | about 6 minutes |
| Classification using four threads | about 6.5 minutes |
| Delivery | less than one minute |
These figures come from one recorded test run and show how the source feed was reduced to a small stream of target alerts.
8. From a Seasonal Example to Continuous Monitoring
Oktoberfest is only one example. The same pattern works for other tasks where the goal is not to collect every post, but to detect a new event with a specific meaning. To adapt the workflow, change the source, filtering criteria, and delivery channel.
| Task | Signal to Detect | Destination |
|---|---|---|
| Lead discovery | a user is looking for a contractor, service, or product alternative | sales team or CRM |
| Brand monitoring | a complaint, refund request, positive review, or comparison | support or marketing channel |
| Support and incidents | a report about an outage, blocking error, or payment problem | on-call team chat |
| Listing monitoring | a new offer, purchase request, or fraud warning | Telegram or a work chat |
When a Simple Filter Is Enough
AI is not necessary in every scenario. If an event can be identified by an exact tag, username, or unambiguous string, ordinary filtering is sufficient.
Semantic analysis is useful when the same intent can be expressed in different words. For example, a contractor request may be phrased as “who would you recommend,” “we are looking for a specialist,” “we need help with a project,” or “who can take on this task.”
How to Change the Prompt for Another Task
You do not have to rebuild the entire chain to repurpose the monitor. Start by defining the event that should trigger an alert, then replace the categories and their definitions in the queryformat field of the redditmon_deepai parser preset.
A reusable template looks like this:
You are a classifier of posts from [SOURCE] for [GOAL].
Categories:
TARGET_1 ([exact definition of the first event]),
TARGET_2 ([exact definition of the second event]),
NO_MATCH (anything else).

Answer with ONE line strictly in the format:
CATEGORY | short fact up to 15 words.

No markdown, no explanations, no lists.
POST: $query
Answer:
For lead discovery, categories may be LEAD, COMPARISON, COMPLAINT, and NO_MATCH. For support, they may be OUTAGE, LOGIN, PAYMENT, and NO_MATCH. For brand monitoring, they may be NEGATIVE, REFUND, PRAISE, and NO_MATCH.
Follow several rules when designing a new prompt:
- One category should correspond to one action. If
LEADandBUYdescribe almost the same intent, the model will confuse them. - Define an event, not merely a topic. “A post about the product” is too broad, while “the author is looking for an alternative to the product” describes a verifiable intent.
- Always keep
NO_MATCH. The model needs a safe option for posts that are related to the topic but not to the target event. - Keep the machine-readable format short. A
CATEGORY | factline is easier to validate and pass to the next task. - Add examples for similar categories. If the model confuses a contractor request with a request for general advice, add several short “post → category” examples immediately before
$query.
Changing the prompt alone is not enough. Add the same category names to the tok = a.match(...) expression in resultsFormat and create appropriate source-text checks for them. If you replace SELL with LEAD only in the prompt, the model will return the new category but the current template will not recognize it.
If you change not only the task but also the source, review the $query format and the title and URL extraction rules. This version expects a line produced by Reddit::Posts and looks for a Reddit URL. Those rules must be adapted for a forum, review site, or another API.
Main Takeaway
The value of this monitor is not that it collects more posts. It does the opposite: it reduces the stream to a few events that require attention.
A-Parser combines the process into one sequence:
collect new posts
→ remove previously seen items
→ determine intent
→ send a concise alert
The r/Oktoberfest example demonstrates this process by looking for available table seats. The same principle applies to leads, reviews, listings, and incident reports.
Start with one source and one event type. The more precisely you define the alert condition, the less noise reaches the recipient.
Appendix: Ready-to-Import A-Parser Preset
Show preset for A-Parser
eNrtWI1v2zYW/1cIoWvszXHs9jbclCsC13Xa7JI4l7g4FHFm0BJta6FFlaTi
umX+9/0eJctKluR2QIfDDisamXx8X3xffOSX4EZok6g0CLutwHJzbc60MMKa
ILz8EmR+HITBuYjjxLITlSZWabbL+kpKEVmWilXQCjKuDfiA5rJEDcMzZcCl
FcRixnNpg9aXwK4zAWYKMnUSCywmMeYZn4tI5Slwghsuc+D80Ll9HN8oXUMN
SIUnsDOtPq21sDoRZkv18gmK3AhPtMWua5OnyceccGEb2ld4GWTlVmWSXgdX
rRLlrVRTLoPQ6lxsYKOCh4E26Ty4vbrasDGHSi85mfryG3Y4PB/0+u9Yxo5O
WdZte/777OiQSaWydpLG4hP7B+t2uvvsmyvtDT4h4SEDddamIRaYc8wmVooS
7MdtLTLJI9EYB2P8S8dBi40D/G+WFFMVr0uCSKVWpPZxkrbJp9hLo9Ni3Red
zoaFyu0U/ownuZYlK4ywOE4xGZy+2acP5pUVzQW/ESOF7c8SuTWuOcTslC/J
ZuU2l0UIdjudPWMFjGM/UTBwWkQcc1kYkmJxa9z3hc8QKwq4GFIwHGq1BMgK
z4CA640TLoNnfr515r8KmiCccWngTgN9Dzm0i6uVws+JFZpDwWFG6gD8JVBp
T8pjcSPklt6zf50nMkbe9GYgOioJH0YZ/obHbbW7uiiE8kpDh406fvJ6eLIl
itWxmm9MIZNlYjE3fZ9/YacVXAuRVfYqjN7TNomkuBAiBc1SaVGJLKSUiqB0
ZCKlFNp6sJdtQXd2dMdBd4GIu1kyH5ZpucHM0xHq0zDtq2UmBW3xgbIkuTHJ
jFIXWXy+DaKeKf1Ek0rt+yz7XjAYV0UrsEpJ89NFsYFMJ4jR70ntJUxd16V0
WsSlfH9+fEdLEBqrsmE60Pqef33gBAtrMxPu7a1Wq3ZhcaTeck/vDa+tmgo9
E8buocztBSTAirlCaNYsdbYp0xu1qVw9Ubu3RqoX7kMtRO8oDN8gAHpH3oNE
iISbxADxJHi4XI1Tzl5RmeKpWQl9p1qUtYJKRR2sK/D+OP1YUPvgaCudzAHL
AfvYhoRo0dhp1Oxz2S7rHQZko8uf2dV3zR3iY+s0Zd1rXP7sqnV1DQxecb0Y
HB+71+8/uP7w5Kx3+sH1jgfnI3c6nJz0Rv13BREsJe4wbhwkzfF42kBGXAvr
ih/jjODWfzDMlPUf4/yOi69xlk+lcOQVfcMpfdyNyqOF0IRgP+M7zjsd8Tf7
WYCtiRYkxyshPkUyj8VDaiyUFdJppZZuniNM/IhHMM1SxYUUnuhpOnUcvrZL
lHMXJzqNJX7SWEuHEib0QhmROqt5tMA6dDTAzxypmkSiUsQIKR/SguCOPjjV
HL9BXfR7lWJmqSLBGlwLp2YzjP3XFD+EHvE0EnI7qg1FvIGJmOQ4/HnDHjBi
vYGQ1e9AFijO47H5rsEdT91lZ/dHxMBmD9N8fX8LOFWvIZXNlC7I6FvS+SFP
1/TbPGgUTiy9flB4/KDw9kHp6IOmS2ZsrXJGejDQsnI9VsLQXKXCr7W/bRRx
QxFT59wEY3HdMA5aNQ8eRytCNCYfPeSW1QJUq0USLRB2FBKoxM7k8zkCxRVk
4JRBs1mijUWzsBSuWw50ZTFQZrSLByRMc+QiYpt+1w6LgpihrKUx2UMo1EBX
0ru5VnnmrJoLS1H/OTecVPKerbmANYxaCtjIFaZy80RL03RLgUys1lAOWcG/
6eaKVVy5RcsSb+dGSaxqWFvKAwqtGQZqVYEQiwdglgsEUG5FYVEp9INJv+I6
JR70S26P+NLN+LWAn9ApJjFlN1q7yOddqizjJKsIY5pqsYsEJK1ElONkXjtM
9ZrVyLw1YqWgVvvbWS6l18hzh0YdjNEGopS1acgYld7tDEsAvGI7VNt2PKgA
UhUDDo0pTcthWVdoNji+GHhYERZb0EZyd79q3GofkgC8Si7K6SNikXZ/mNSy
gNcklyFHDO+xuk/ri35dZ/L9Y3T+t/gCtcB4/pzl7Q792NIL/uwhv7Q71am3
Mx67nRbb2d1p1mEpwdhdmN7Aas313ztNz3pp5nSGsQkwHP4mpbDtPC+VIEzH
EGT7rDyIK9W/Rt/94q+++4/su0/V/6jRvgy4WaeRXWjBY9xpX1z93tZ7hPN6
rvnyz9V6f52Ourb3ekd9KmwYvhuNzn7XM8jTzw73sedKxX3l5yX2JW7gV//1
Q0j3CYoljlAV155azoYXo6feWmY+j8uHkS3ZswiKsmeAZ4hl0f7FqPQpNj58
C141LptbAM+Sti0NjvvCfG+q7Png7LjXH0z+fTR6NxkNjgdvz3snk9fD0WQ0
/OfgdA/dbXyCrpbPxVOC6e2jJjFC/zRJ4lcPc++/640mR2+eUyF79Wx7fXn0
WQeXHG+ISfF6gl9A0KTzqkR/lSeRl3+V5v/L0vxwIU7RIv6Hilsa709Xcq+q
alq9SX+5/0oByG+eKQCrV5Aw+IC7GC6g6Jui4ukjEZqpGSvruH9eZXyqcstq
Ly5t1i/UhNoho46aNXClYDxHVdQsMay88bLyOthi/jrIsMiZv6ex2m2/2WLo
jlljc9OxinpiQMvudbtCd6CygcWyb1DZ5upRqskZqjkELIGwebBgDRDYBSEh
JUSzzXr+QYatErtgw9MBg7KCFTcNuWZJymg7hZVC1u+NBm+H5x/QNRrsz7IZ
jyzLM1K0+z1bKR2bNjtVbMn1daxWaYulCs08+tbUb9B4gExgzPY4paMiZEXN
GKeFJiFcf+eICIMNwrPi8WhMD4x0+8Qmsfpjh4KFqrCxa7kpyT7/YiHpFMzs
rjJmt/uiM/URWzviwuBl0YsUp2qZpn7SXwh4TPuUj2gc3N6iDvxizop4o7yh
aLu9kxG3vwKjna+xWhere the DeepAI Prompt Is Stored
The TEMPLATE already contains all the required settings. In the Reddit Monitor - Classify task, queryFormat contains only $query. It passes the Reddit data line to FreeAI::DeepAI unchanged.
The complete prompt is stored separately in the queryformat field of the redditmon_deepai parser preset. When classification runs, A-Parser substitutes the incoming post line for $query in this instruction:
You are a classifier of Reddit posts about Oktoberfest. Categories: SELL (the author is selling tickets, seats or a table reservation), BUY (looking to buy), COMPANY (looking for company), ALERT (warning about a problem), NO_MATCH (anything else). Answer with ONE line strictly in the format: CATEGORY | short fact up to 15 words. No markdown, no explanations, no lists.
POST: $query
Answer:
You do not need to copy the prompt manually after importing the preset. Edit queryformat in redditmon_deepai only when you want to change the categories or adapt the monitor to another task.
How to Configure the Telegram Bot and Recipient
Open the third task, Reddit Monitor - Telegram, and locate the Net::HTTP settings. Replace two placeholders:
- In
queryformat, replaceREPLACE_WITH_TELEGRAM_BOT_TOKENwith the token obtained from @BotFather:
https://api.telegram.org/botREPLACE_WITH_TELEGRAM_BOT_TOKEN/sendMessage
- In
body, replaceREPLACE_WITH_TELEGRAM_CHAT_IDwith the recipient:
chat_id=REPLACE_WITH_TELEGRAM_CHAT_ID&text=$query.orig
To find the chat_id, send any message to the bot, then open https://api.telegram.org/bot<TOKEN>/getUpdates in a browser and locate message.chat.id. A group ID is usually negative. For a channel, you can use an ID such as -100… or @channelusername. The bot must be added to the channel with permission to post messages.
Do not publish an export after inserting the token. Use only a TEMPLATE with placeholders when downloading or sharing the preset.
Before the first run:
- open the spoiler above, copy the preset code, and import it into A-Parser;
- in the first task, verify that
posts.linkresult deduplication uses the String type; create the persistentredditArticleSeendatabase and select it in Keep unique; - enter the Telegram bot token and
chat_idas described above; - verify that the classifier uses the
redditmon_deepaiparser preset and that the result template extracts the category witha.match(...); - run a small test first without sending alerts to everyone at once, review the model responses and
step2.txt, then send one known-positive post.
The published TEMPLATE was decoded and checked: it does not include a Telegram token, chat ID, or proxy credentials. Do not distribute the working file containing the bot credentials.
To use the chain for another community, replace the URL in the first task and the rules in the second task’s prompt. The input-line format and task links can remain unchanged.
Recommended Stack:
- A-Parser Pro / Enterprise
Use A-Parser to collect and extract content in parallel. Running a custom JavaScript/TypeScript parser requires a license that supports custom parsers; see the purchase page for current terms. - A-Parser Unlimited Proxies
Proxies can help maintain stable collection and handle a larger number of requests in parallel.