
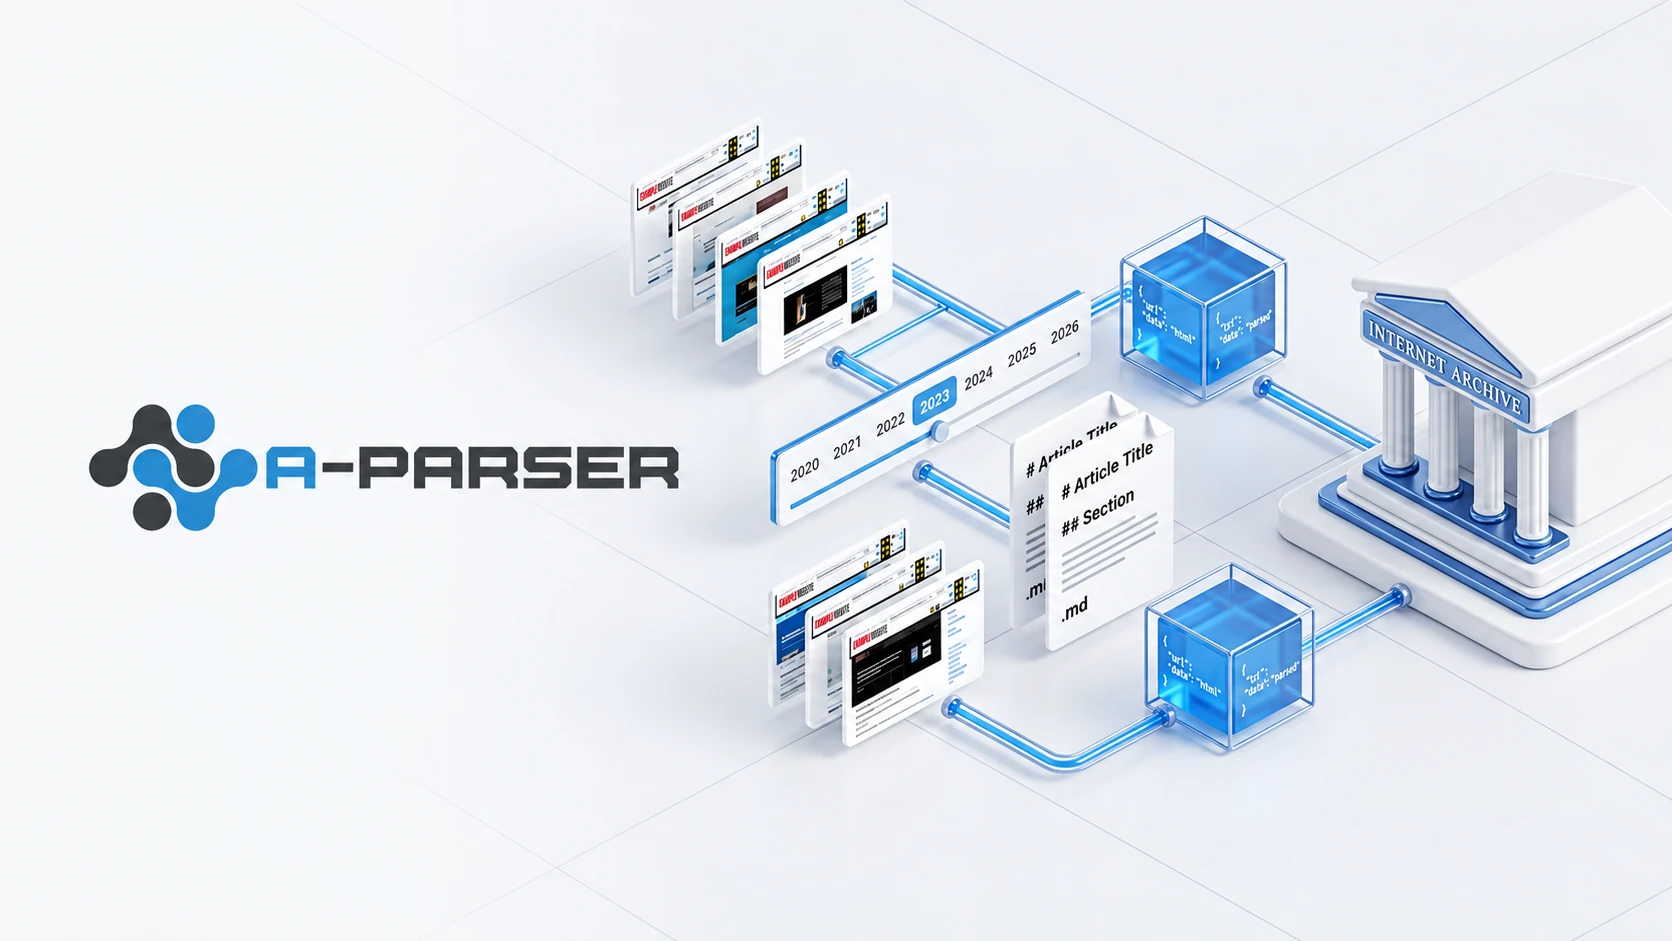
Scraping Archive.org with A-Parser: Extract Thousands of Articles from the Wayback Machine
Practical guide to scraping Archive.org and the Wayback Machine with A-Parser. Covers the CDX API, clean id_ snapshot retrieval, a no-code Net::HTTP → HTML::ArticleExtractor workflow, and a custom TypeScript scraper with Markdown, JSONL, and raw HTML export.