 FreeAI::Alice - Alice AI Scraper
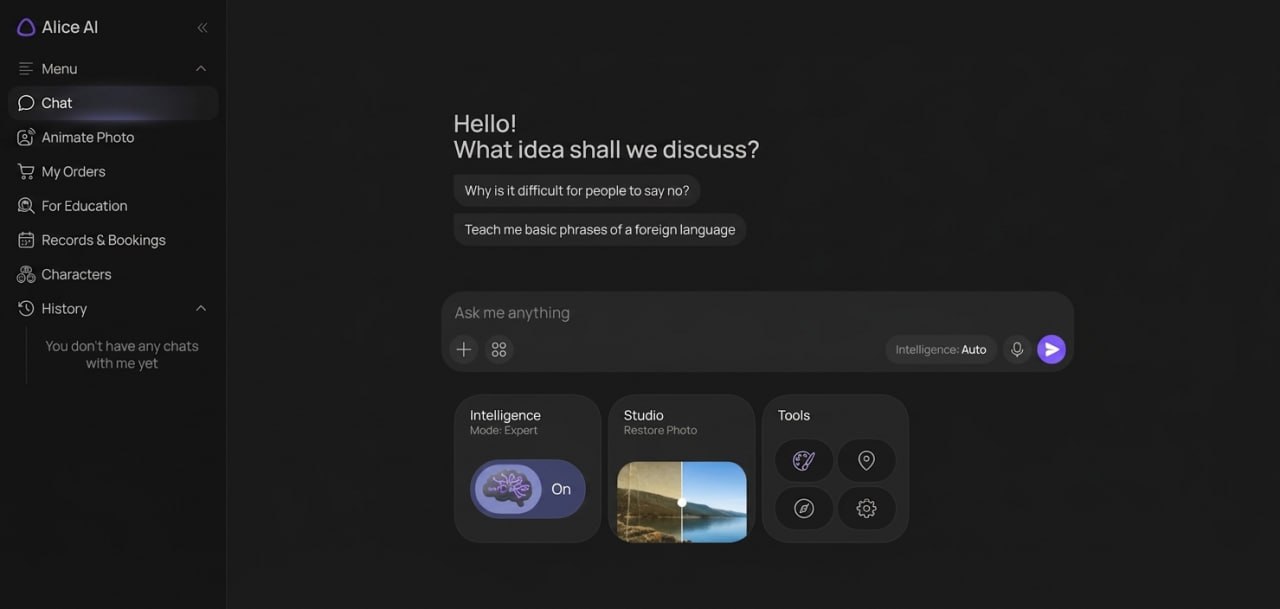
Scraper overview
The Alice scraper retrieves responses from the Alice AI via the alice.yandex.ru website, along with a list of sources it relies on. The result includes the response text and source cards: address, title, and description.
Queries are written in natural language, just like a message in the Alice chat. No registration is required: the scraper opens the main page and obtains the session identifier automatically.
Results can be saved in the desired format using the Template Toolkit engine: text, CSV, or JSON.
Data collected
- Response text
- Links, titles, and descriptions of sources
Capabilities
- Natural language queries
- Advanced response mode
- Collecting sources separately from the response text
Use cases
- Collecting answers for thematic queries for knowledge bases, content plans, and FAQs
- Extracting source links with titles and descriptions
- Monitoring topics with reference to pages cited by Alice
- Quickly checking which sites Alice considers sources for a query
Queries
Queries are specified as text, as if written in the Alice chat, for example:
Dollar to ruble exchange rate today
Can you give links to new movies 2026 any movies
What is a scraper?
Results
By default, the query and answer are output:
$query
$answer
Example:
Can you give links to new movies 2026 any movies
Sure! Here are some interesting movies expected in 2026:

1. **Josephine** - drama, USA
2. **Wild Horse** - drama, UK
3. **Spider-Man: Brand New Day** - action, USA
...
Sources are not included in this text. They are located in the $p1.sources array.
Output results examples
Answer and sources
Result format:
ANSWER:
$p1.answer

SOURCES:
$p1.sources.format('Type:$type \n Link: $link \n Anchor:$anchor \n Snippet:$snippet\n')
Example result:
ANSWER:
Sure! Here are some interesting movies expected in 2026:
...

SOURCES:
Type:source
 Link: https://www.film.ru/a-z/movies/2026
 Anchor:Best movies of 2026
  Snippet:We have collected 2026 movies for you based on ratings from Film.ru authors
Type:source
 Link: https://www.afisha.ru/movie/y2026/
 Anchor:Movies and TV series of 2026- Afisha-Kino
  Snippet:Movies and series of 2026: choose cinema by genre or rating...
Exporting a list of links
Result format:
$p1.sources.format('$link\n')
Example result:
https://www.film.ru/a-z/movies/2026
https://www.afisha.ru/movie/y2026/
https://www.kinoafisha.info/releases/2026/
https://ru.wikipedia.org/wiki/Категория:Фильмы_2026_года
CSV output of links, titles, and descriptions
Result format:
[% FOREACH item IN p1.sources;
tools.CSVline(loop.count, item.link, item.anchor, item.snippet);
END %]
Example result:
1,https://www.film.ru/a-z/movies/2026,"Best movies of 2026","We have collected 2026 movies for you based on ratings from Film.ru authors"
2,https://www.afisha.ru/movie/y2026/,"Movies and series of 2026 - Afisha-Kino","Movies and series of 2026: choose cinema by genre or rating"
Specify the csv extension in the results filename.
Possible settings
| Parameter | Default value | Description |
|---|---|---|
| Request retries | general task setting | How many times to retry the request if no response is received. The next proxy is used before retrying |
| Session retries (busy answer) | 3 | How many times to retry the request in the same session if Alice responds that she is busy |
| Retry delay, seconds | 5 | Pause in seconds before such a retry |
| Save sessions (skip page reload) | ☑ | Save the session and do not reload the main page |