 SE::DuckDuckGo - DuckDuckGo Search Engine Scraper
Scraper overview
A scraper for DuckDuckGo search results. Thanks to the DuckDuckGo scraper, you can obtain large databases of links ready for further use. You can use queries in the same format as you enter them in the DuckDuckGo search bar, including search operators (intitle, inurl, site, etc.). More details on the official DuckDuckGo Search Syntax page.
A-Parser functionality allows you to save DuckDuckGo scraper settings for future use (presets), set scraping schedules, and much more. You can use automatic query multiplication, substitution of subqueries from files, brute-forcing of alphanumeric combinations and lists to obtain the maximum possible number of results.
Saving results is possible in the form and structure you need, thanks to the built-in powerful Template Toolkit template engine, which allows applying additional logic to results and outputting data in various formats, including JSON, SQL, and CSV.
Collected data
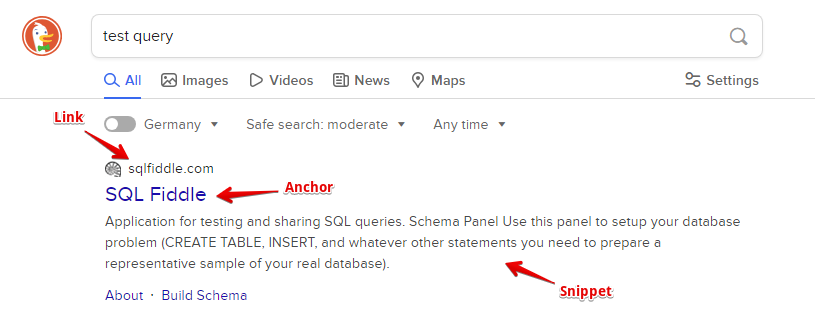
- Links, anchors, and snippets from search results (
$serp.$i.link,$serp.$i.anchor,$serp.$i.snippet) - Links, visible links, anchors, snippets, domain, and ad position from advertising results (
$ads.$i.domain,$ads.$i.link,$ads.$i.visiblelink,$ads.$i.anchor,$ads.$i.snippet,$ads.$i.position,$ads.$i.page) - List of related keywords (
$related.$i.key)
Capabilities
- Support for all DuckDuckGo search operators (intitle:, inurl:, site:, etc.). More details about search operators on the official DuckDuckGo Search Syntax page
- Specification of the number of pages (from 1 to 10)
- In addition to organic results, ad blocks and related keywords are collected
- Ability to scrape by a selected region (Region option) and specify the results language (Language option)
- Ability to enable safe search (Safe search option) and limit results by time (Serp time option)
- Separate HTTP/2 enablement for the search page and for the results data request
- Automatic switch to the built-in browser if DuckDuckGo does not return results data via HTTP
Use Cases
- Collecting link databases - for A-Poster, XRumer, AllSubmitter, etc.
- Checking website indexing
- Searching for backlinks (mentions) of websites
- Any other options involving DuckDuckGo scraping in one form or another
Queries
You should specify search phrases as queries, for example:
Football
test
site:a-parser.com
scraper site:a-parser.com
test -site:tests.com
IoT filetype:pdf
Query substitutions
You can use built-in macros for query multiplication; for example, if we want to get a very large database of forums, we specify several main queries in different languages:
forum
forum
foro
论坛
In the query format, we specify a character brute-force from a to zzzz; this method allows for maximum rotation of search results and obtaining many new unique results:
$query {az:a:zzzz}
This macro will create 475254 additional queries for each original search query, which in total will give 4 x 475254 = 1901016 search queries—an impressive figure, but no problem at all for A-Parser. At a speed of 2000 queries per minute, such a task will be processed in just 16 hours.
Using operators
You can use search operators in the query format, so they will be automatically added to each query from your list:
site:$query
Output results examples
A-Parser supports flexible result formatting thanks to the built-in Template Toolkit template engine, which allows it to output results in any form, as well as in structured formats like CSV or JSON.
Link list export
Links + anchors + snippets with position output
Outputting links, anchors, and snippets to a CSV table
Saving related keywords
Outputting ad blocks
Saving in SQL format
Result dump to JSON
Results processing
A-Parser allows processing results directly during scraping; in this section, we have listed the most popular cases for the DuckDuckGo scraper.
Link deduplication
Link deduplication by domain
Extracting domains
Removing tags from anchors and snippets
Filtering links by inclusion
Possible settings
| Parameter name | Default value | Description |
|---|---|---|
| Pages count | 5 | Number of pages to scrape (from 1 to 10); scraping may end earlier if the search results have no next page |
| Region | US (English) | Selection of the search results region |
| Language | English (United States) | Selection of the search results language |
| Safe search | Moderate | Safe search: Strict, Moderate, or Off |
| Serp time | Any time | Search period: past 24 hours, week, month, year, or any time |
| Use HTTP/2 | ☐ | Determines whether to use HTTP/2 instead of HTTP/1.1 when requesting the search page |
| Use HTTP/2 for links | ☐ | Same for requesting search result data |
| User agent | Chrome 150, Windows | User-Agent header when requesting pages, also used in the browser. If left empty, the User-Agent of the current Firefox version will be used |
| Get first link with browser pages count | 5 | How many built-in browser pages can be used simultaneously. The browser is only needed to obtain the search page: if DuckDuckGo did not return result data via HTTP, the next attempt is performed via the browser |